Our Work · Research prototype
VERIFAI: checking the facts inside an AI agent's actions.
A research prototype that checks a purchase order prepared by an AI agent against its source documents before the order goes out. If it can't find the evidence, it hands the order to a person instead of guessing.
Watch: VERIFAI in 34 seconds
Research prototype. Synthetic scenarios. Not commercially validated. The comparison and decision screens are real testbed output on a synthetic order; footage of people and places is AI-generated.
The question
AI agents are starting to read supplier quotes and prepare purchase orders. Most guardrails check whether an action is allowed: is the supplier approved, is the amount under the limit? VERIFAI asks a different question: are the facts inside the action actually supported by the source documents?
A wrong price, quantity, part revision or supplier can pass every permission check and still cost a small business real money.
How it works
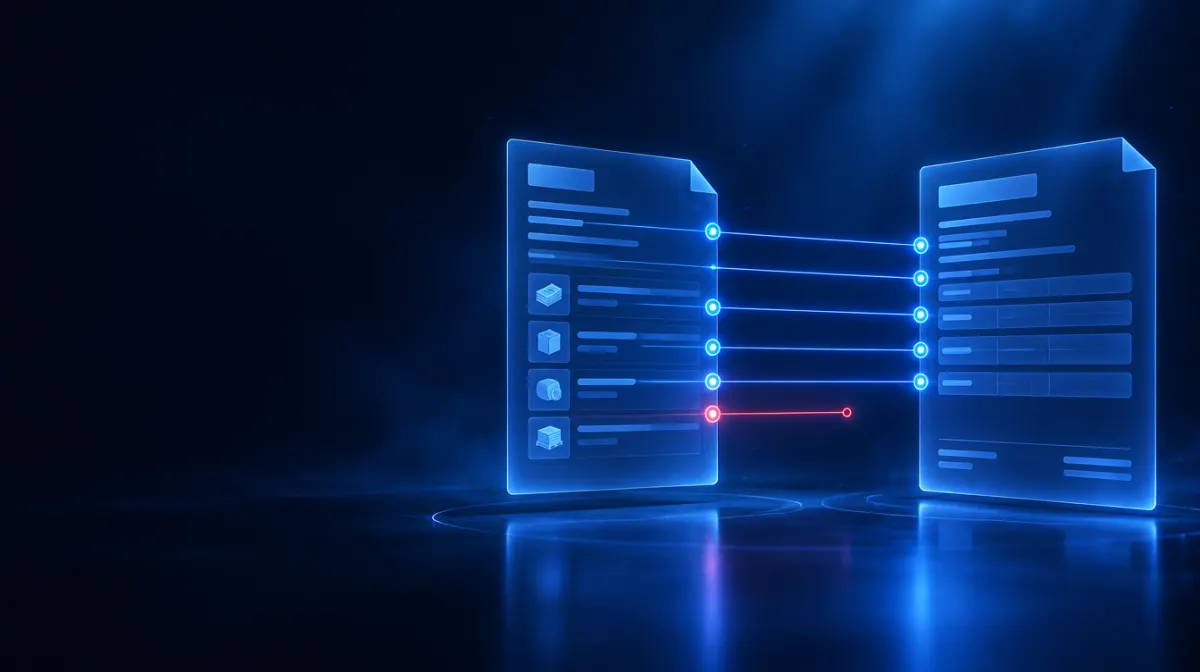
- Splits a proposed purchase order into individual claims: price, quantity, unit of measure, part number and revision, supplier, currency, quote validity, totals and approval
- Checks each claim against the document or record it should come from, such as the supplier quote, the approval record or the approved-supplier list
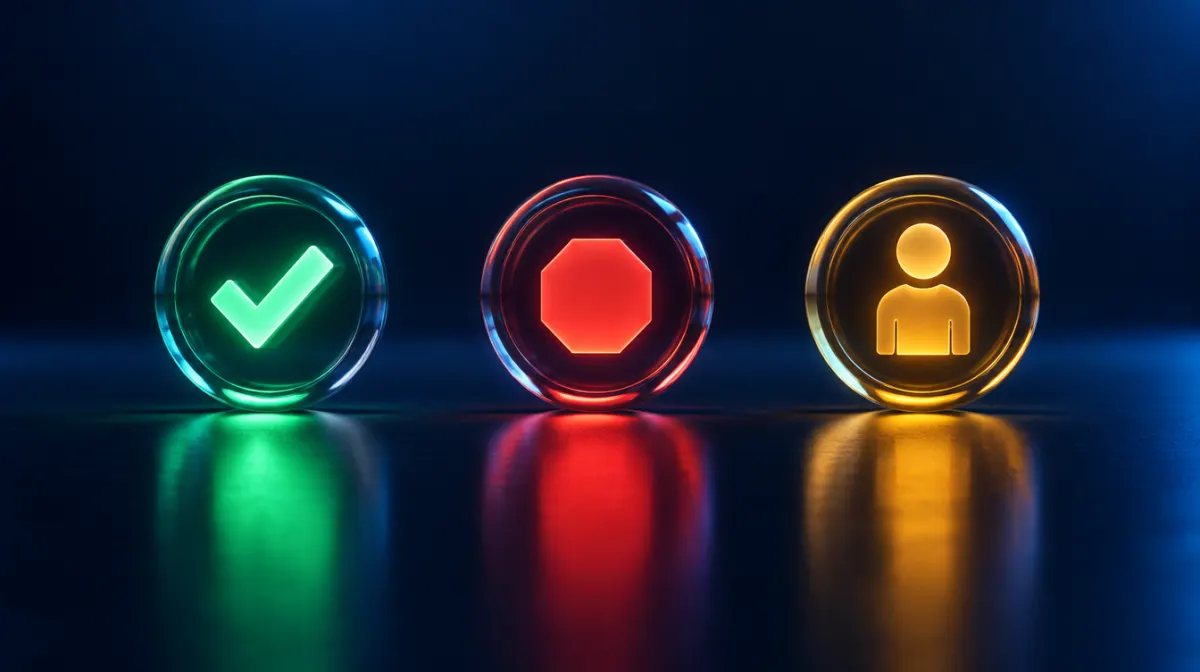
- Decides one of three things: allow when every claim is supported, block when a claim contradicts its source, or escalate to a person when the evidence is missing or unreadable
- Gives a short, readable reason for every decision
What we tested
A testbed of synthetic purchase-order scenarios: generated supplier quotes in several layouts, optional approval records, and the order an agent proposes from them. We seeded 13 types of error (wrong price, quantity, unit, part revision, supplier, currency, expired quote, bad arithmetic, missing or insufficient approval, unapproved supplier, unsupported claims and missing source documents) alongside clean orders.
We compared four set-ups: no checking, permission-style rules only, evidence checks only, and the two combined. A separate held-out set uses a quote layout the prototype had never seen.
Verified results
Reproduced in October 2026 from the testbed code: 480 synthetic scenarios per set, four random seeds. The same author wrote the scenarios, the errors and the checks, so these numbers show the method works on the errors it was designed for. They are not evidence of real-world accuracy.
Limits
- Unfamiliar documents. On a quote layout it had never seen, the prototype couldn't read the quote and escalated instead. That fails safe, but it would send about half of good orders to a person. This is the main open problem.
- Synthetic data only. No real quotes, orders, customers or suppliers have been used.
- Not yet compared with an AI-judge baseline or with published agent guardrail research.
- No users yet. VERIFAI is not a product and is not for sale.
Project status
Research prototype, October 2026. Next steps: independently written test cases, reading unfamiliar document layouts reliably, and testing alongside real ordering in "shadow mode," where VERIFAI only observes and nothing it decides is acted on.
Interested in the research?
If you run purchasing for a small business and would like to talk about how quote and order mistakes happen in your work, we'd like to hear from you.